Data Capture, Provenance, and Management
JFAB’s data management ecosystem enables the generation of FAIR-compliant, standardized datasets.
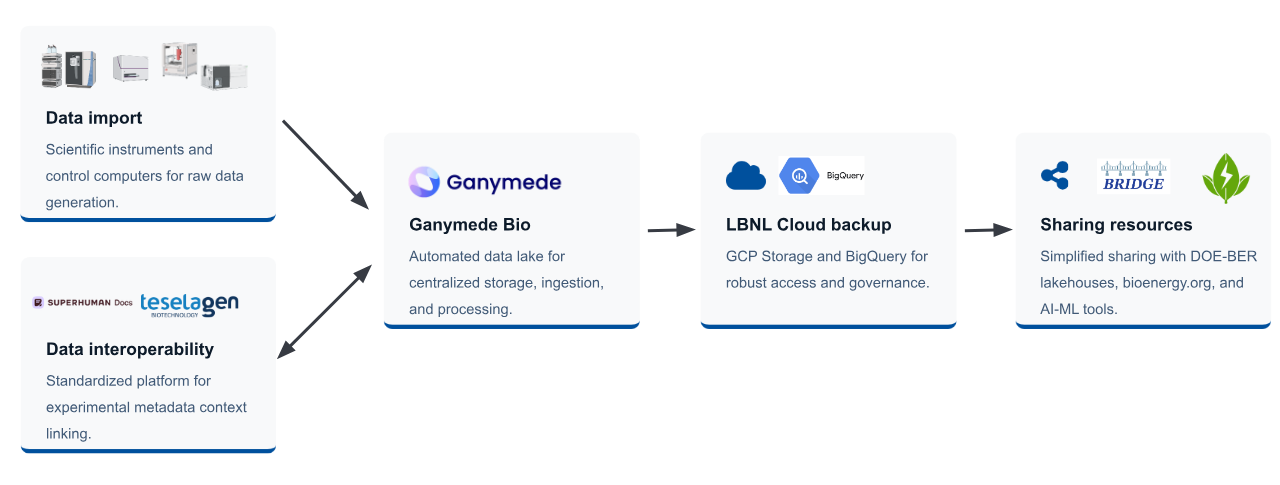
JFAB’s data management pipeline
How it works:
JFAB leverages a digital stack specifically optimized to eliminate data silos for the entire research ecosystem.
- Bench scientists use Superhuman Docs and TeselaGen for metadata entry and design management. At the same time, AI agents work autonomously to generate metadata about experiments.
- Raw data is then captured by Ganymede, which delivers insights back into the Superhuman Docs interface.
- Data is backed up in the Lawrence Berkeley National Laboratory (Berkeley Lab) Google Cloud.
- Beyond the bench, Ganymede serves as a data bridge, disseminating standardized information to Bioenergy.org, U.S. Department of Energy data lakehouses and autonomous agents for high-level modeling.
All data is FAIR (findable, accessible, interoperable, reusable) compliant, enabling a seamless and machine-readable flow of “clean” information that serves the diverse needs of individual bench researchers, data scientists, and autonomous agents.
The overall architecture enables scalability, reproducibility, and AI-ready science.